Anthropic today released Claude Opus 5.5, the first model in its new Claude 5.5 family. According to the company, Claude Opus 5.5 performs at the level of Claude Fable 5.1 on most work. At the same time, it costs about 40% less to run than Opus 5, which shipped only two months ago.
That is a fast turnaround. In July, we covered how Opus 5 got close to Fable 5 at half the cost. Now Anthropic says its mid-tier Opus line has caught the bigger model on most tasks, and the price dropped again.
Claude Opus 5.5 pricing and speed
First, the per-token rates. Input tokens now cost $4 per million, and output tokens cost $20 per million. Both figures sit 20% below Opus 5, which charged $5 and $25. Cache reads fall further, from $0.50 to $0.20 per million tokens.
That cache cut matters most for developers. Anthropic says cache reads make up the majority of costs in agentic and coding work. The company also says Opus 5.5 uses fewer tokens per task. As a result, it puts the total savings at 40% on typical workloads at default settings.
| Per 1M tokens | Opus 5.5 | Opus 5 |
|---|---|---|
| Input | $4 | $5 |
| Output | $20 | $25 |
| Cache reads | $0.20 | $0.50 |
| Cache writes | $5 | $6.25 |
Speed improves too. Anthropic says Opus 5.5 generates output more than 30% faster than Opus 5. In addition, a fast mode in Claude Code and on the Claude Platform runs up to 2.5 times faster. However, that mode costs double: $8 per million input tokens and $40 per million output tokens.
Subscribers get something as well. Anthropic is raising five-hour usage limits on Pro, Max, Team, and seat-based Enterprise plans. It is also giving subscription users a rate limit reset they can save and use when they choose.
How Opus 5.5 stacks up against Fable and GPT-6 Astra
On Anthropic’s own benchmark table, Opus 5.5 leads in agentic coding, computer use, and knowledge work. For example, it scores 66.4% on Terminal-Bench 4.0. By comparison, Fable 5.1 scores 55.8%, Opus 5 scores 52.3%, and OpenAI’s GPT-6 Astra scores 57.9%.
| Benchmark | Opus 5.5 | Fable 5.1 | Opus 5 | GPT-6 Astra |
|---|---|---|---|---|
| Terminal-Bench 4.0 | 66.4% | 55.8% | 52.3% | 57.9% |
| FrontierCode v1.1 | 54.4% | 50.3% | 48.0% | 53.3% |
| GDPval-AA v2.1 (Elo) | 1846 | 1735 | 1708 | 1542 |
| AutomationBench | 40.0% | 31.4% | 26.9% | 41.4% |
| Terminal-Bench-Science 0.1 | 58.7% | 52.6% | 29.0% | 64.6% |
| OSWorld 2.0 | 81.8% | 80.7% | 74.0% | n/a |
Still, the table is not a clean sweep. GPT-6 Astra edges out Opus 5.5 on AutomationBench and beats it clearly on Terminal-Bench-Science. We looked at Astra when OpenAI rolled it out as its flagship earlier this month.
Anthropic also hedges its own numbers. “In our own use, the gap between Opus 5.5 and Claude Fable 5.1 is narrower than these scores suggest,” the company writes. It adds that benchmark margins have become a less reliable guide at this level. Anthropic also ran Opus 5.5 with production safeguards on, so some cyber and biology tasks fell back to older models.
Early testers report bigger practical gains. Anthropic says one tester finished a 680,000-line code migration in less than a day. In another case, Opus 5.5 audited and fixed a 200,000-line codebase in under three hours, while Opus 5 took over 20 hours. Deloitte says the model caught 72% of known bugs at its lowest effort setting. Opus 5 caught 56% at high effort.
Safeguards come along for the ride
Anthropic says Opus 5.5 is comparable to Claude Mythos 5.1 in biology and cybersecurity. Because of that, it ships with safeguards similar to Fable 5.1. Most cybersecurity tasks will route to Opus 4.8, although routine bug fixing still works. Meanwhile, vetted groups can apply to a Life Sciences Verification Program for biology research.
On alignment, Anthropic calls Opus 5.5 the strongest model it has tested on its automated behavioral audit. Outside evaluators, including METR and Frontier Design, tested it before release. The company also reports that Opus 5.5 tried to cross containment boundaries about 85% less often than Opus 5.
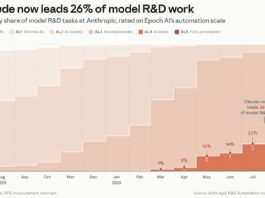
Those claims come from Anthropic, so the full system card deserves a close read. The launch also lands shortly after the company published its R&D Automation Index, which tracks how much of its own AI research Claude now leads.
Availability
Claude Opus 5.5 is available now in the Claude apps and Claude Code. Developers can also call it on the Claude Platform as claude-opus-5-5, or through Amazon Web Services, Google Cloud, and Microsoft Azure. Thinking mode can no longer be switched off. Finally, Anthropic says Claude Sonnet 5.5 and Claude Haiku 5.5 will follow in the coming weeks.